examstrack logo

You manage a Microsoft Foundry project.
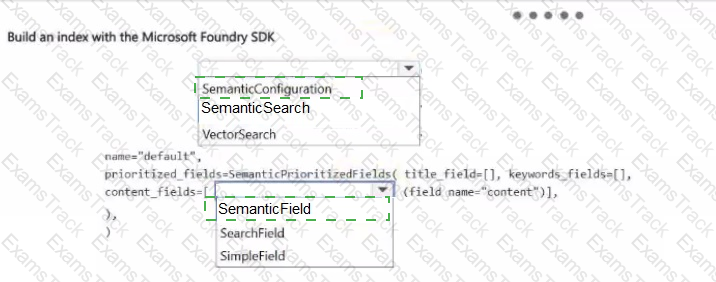
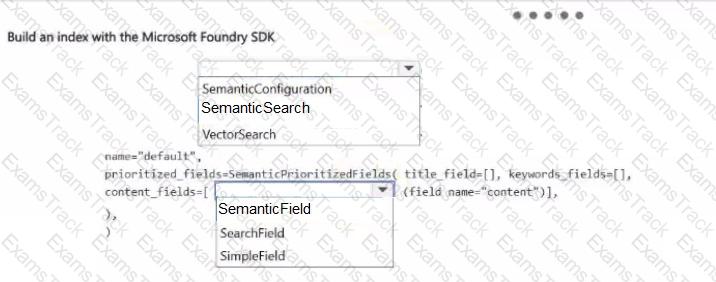
You plan to create a search index by using the Microsoft Foundry SDK.
You need to configure the Content field as a prioritized field for semantic ranking. The field is already set to be searchable.
How should you complete the item code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
You are planning to register a trained model in an Azure Machine Learning workspace.
You must store additional metadata about the model in a key-value format. You must be able to add new metadata and modify or delete metadata after creation.
You need to register the model.
Which parameter should you use?
You train and publish a machine teaming model.
You need to run a pipeline that retrains the model based on a trigger from an external system.
What should you configure?
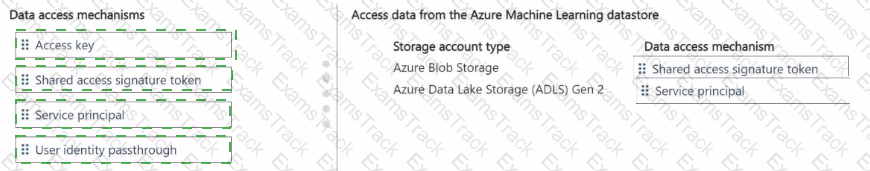
You manage an Azure Machine Learning workspace That has an Azure Machine Learning datastore.
Data must be loaded from the following sources:
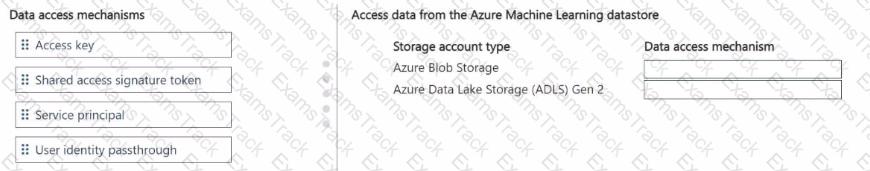
• a credential-less Azure Blob Storage
• an Azure Data Lake Storage (ADLS) Gen 2 which is not a credential-less datastore
You need to define the authentication mechanisms to access data in the Azure Machine Learning datastore.
Which data access mechanism should you use? To answer, move the appropriate data access mechanisms to the correct storage types. You may use each data access mechanism once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
You manage an Azure OpenAI deployment of the gpt-4o base model.
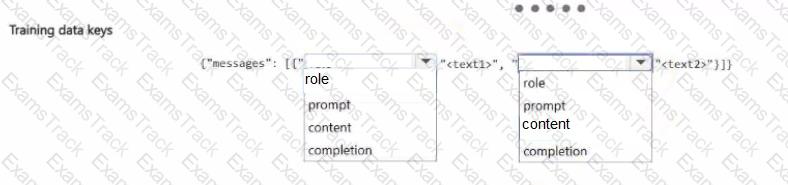
You plan to fine tune the deployed model.
You need to prepare a file that contains training data.
Which keys should you include in each line of the training data file? To answer, select the appropriate options in the answer area
NOTE: Each correct selection is worth one point.
-
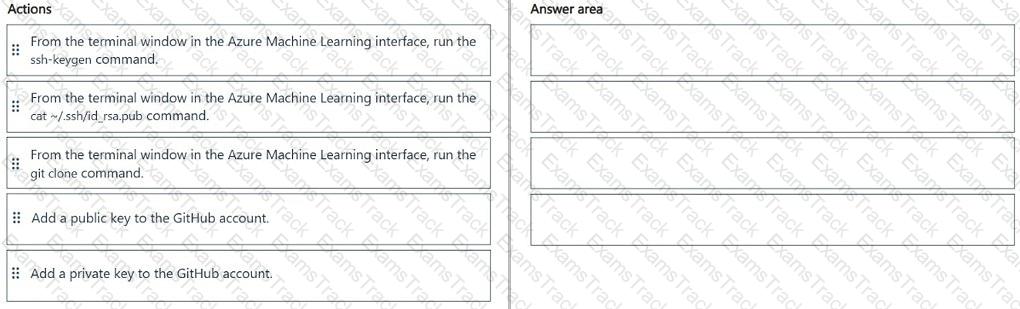
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.
You use the Azure Machine Learning SDK v2 for Python and notebooks to train a model. You use Python code to create a compute target an environment and a training script You need to prepare information to submit a training job. Which class should you use?
You have an Azure Machine Learning workspace.
You have the following code:
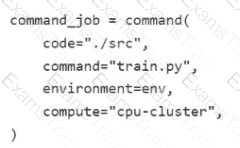
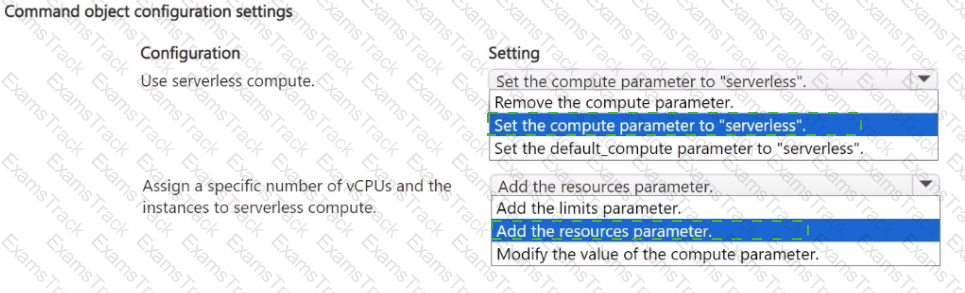
You plan to rely on serverless compute to train a model by using Azure Machine Learning Python SDK v2. The serverless compute must use a designated number of nodes of a specific virtual machine type.
You need to modify the code to run the training job according to the plan.
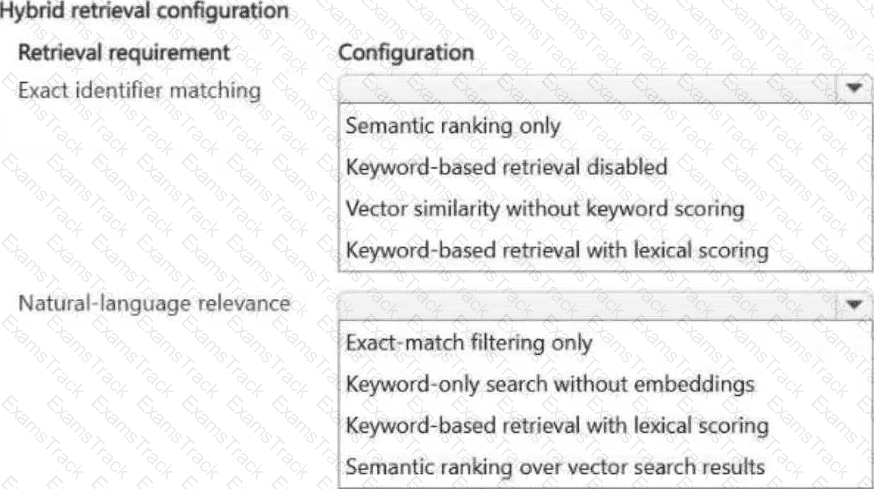
How should you modify the command object? To answer, select the appropriate oations in the answer area.
NOTE: Each correct selection is worth one point.
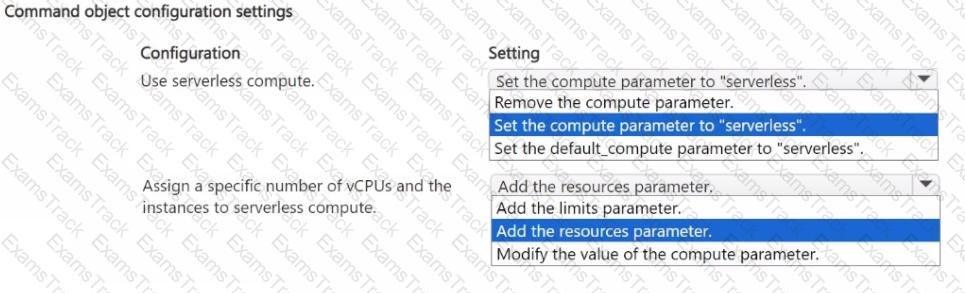
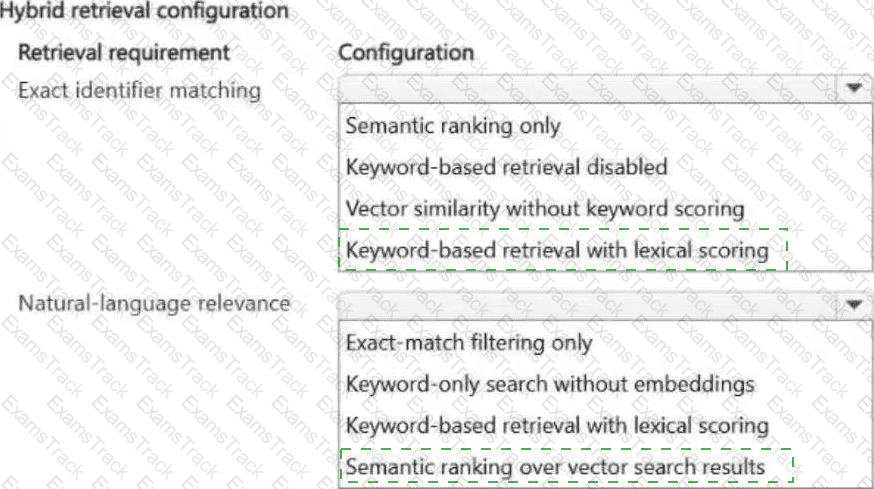
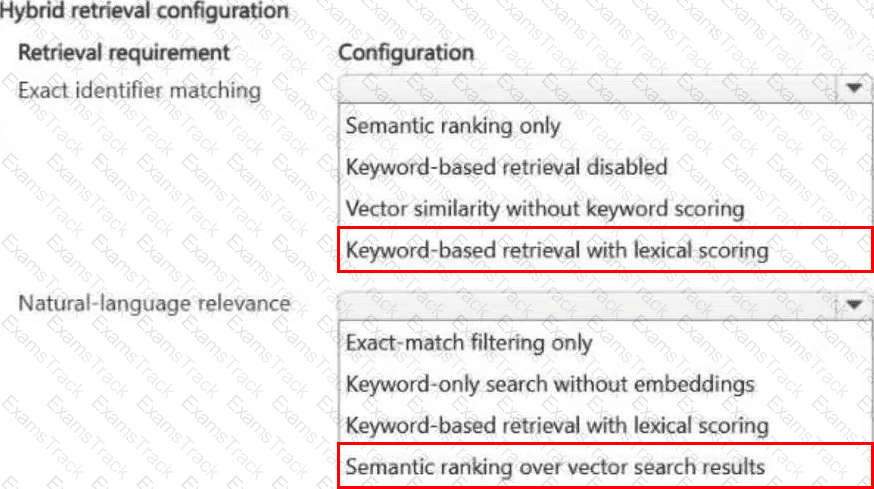
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.
The system must support the following retrieval requirements:
Queries that include exact policy identifiers must return matching documents even when semantic similarity is low.
Natural-language questions must prioritize semantically relevant documents even when keywords are not an exact match.
You need to configure the retrieval approach to meet the requirements.
How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
You manage an Azure Machine Learning workspace.
You experiment with an MLflow model that trains interactively by using a notebook in the workspace. You need to log dictionary type artifacts of the experiments in Azure Machine Learning by using MLflow. Which syntax should you use?
|
PDF + Testing Engine
|
|---|
|
$45 |
|
Testing Engine
|
|---|
|
$35 |
|
PDF (Q&A)
|
|---|
|
$30 |
Microsoft Free Exams |
|---|

|

Copyright © 2026 Examstrack. All Rights Reserved

TESTED 20 Nov 2026