examstrack logo
You need to recommend an experiment-tracking strategy that ensures consistent experiment results.
What should you recommend?
Fabrikam Inc. needs to improve the performance of a GPT-5 model based on the stated technical requirements.
Which action should you perform first?
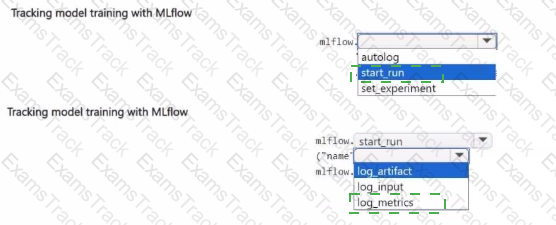
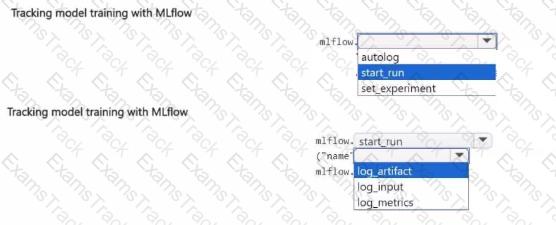
You manage an Azure Machine Learning workspace.
You train a model interactively with a Jupyter Notebook in the workspace During training, a dataset is created with accuiacy and loss metrics for each epoch.
You need to configure model tracking with MLflow to log the dataset created during the training.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
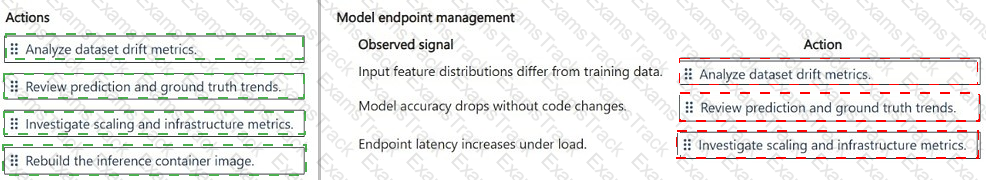
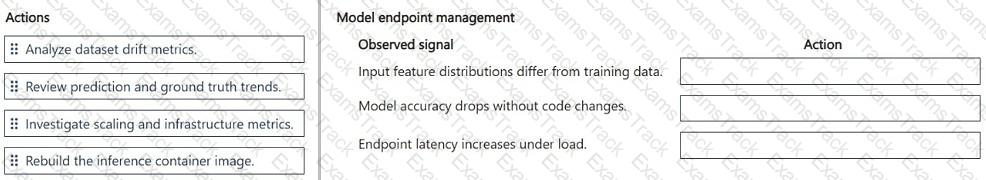
A team deploys a classification model to production and scores incoming customer data daily.
After several weeks, business stakeholders report unexpected changes in prediction behavior, even though the endpoint remains healthy.
You need to determine whether data drift is occurring and if it is, identify the appropriate actions.
Which action should you perform for each observed signal? To answer, move the appropriate actions to the correct observed signals. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
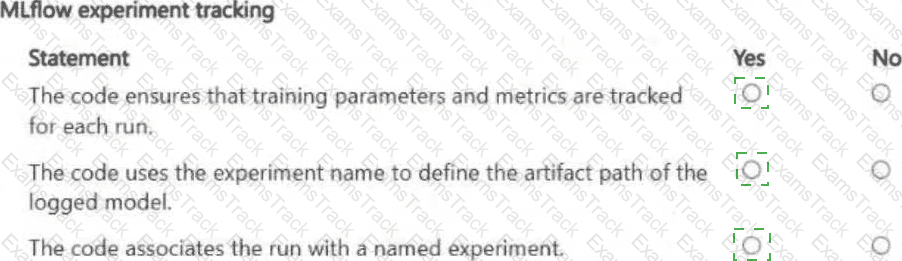
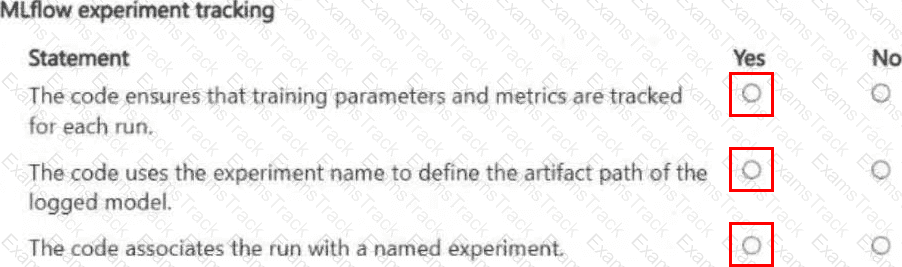
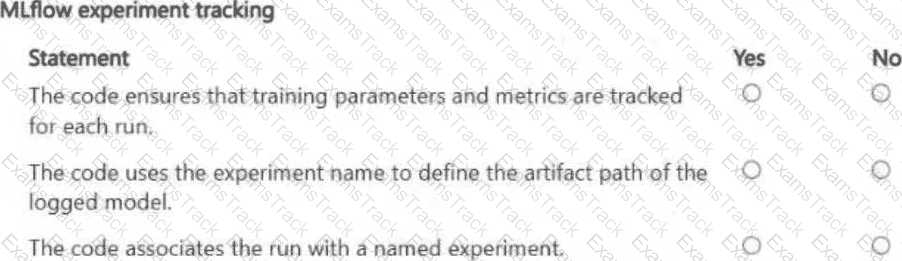
You train a model in Azure Machine Learning.
You plan to capture experiment details for later comparison. The training code must log parameters and metrics for each run.
You review the following training script.
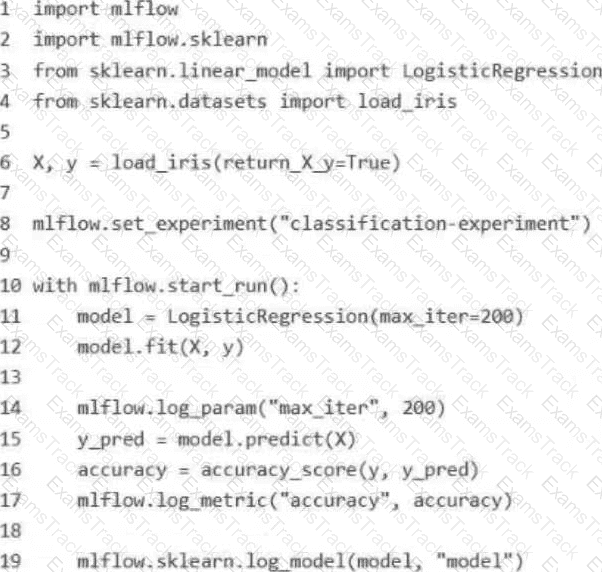
You need to verify whether the training script meets the experiment tracking requirement.
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
You need to standardize how Fabrikam Inc. manages machine learning assets.
Which action should you perform first?
You are designing a new machine learning solution to predict customer churn by using Azure Machine Learning. You have raw data in CSV format stored in Azure Data Lake.
You need to design the solution so that it can efficiently handle large-scale model training and iterative development.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point
You train and publish a machine teaming model.
You need to run a pipeline that retrains the model based on a trigger from an external system.
What should you configure?
|
PDF + Testing Engine
|
|---|
|
$52.5 |
|
Testing Engine
|
|---|
|
$40.5 |
|
PDF (Q&A)
|
|---|
|
$34.5 |
Microsoft Free Exams |
|---|
|
Copyright © 2026 Examstrack. All Rights Reserved
TESTED 15 Sep 2026